Skip to content

What the November 2026 Microsoft Outage Taught Us

At about 11 a.m. Toronto time on Thursday, November 12, Outlook stopped delivering mail. Within the hour, Teams meetings were dropping, Copilot was unresponsive, and IT teams who went to check device status in Intune found they could not get in either. For most offices in the GTA, that was the middle of a normal working day, and it stayed broken well into Friday.

Microsoft says it was not a cyberattack, and it has not yet published a full root cause. But you do not need the root cause to learn from it. Here is what the outage taught us, and what we are changing with clients because of it.

The short answer: the outage proved that for most mid-sized businesses, Microsoft 365 is a single point of failure for email, meetings, files, security tooling and device management all at once. You cannot prevent a Microsoft outage, but you can decide in advance how your people will communicate, what your IT team can still do, and how long the business can run without it.

Moving off Microsoft is not the lesson. The lesson is that your continuity plan probably assumes your office or server fails, not your cloud provider. Add three things: a way to reach staff that does not run on Microsoft 365, offline copies of your critical runbooks and contacts, and a written decision on what the business does at the 2-hour, 8-hour and 24-hour mark.

Cloud concentration risk

Cloud concentration risk is the exposure a business takes on when many critical functions (email, chat, file storage, identity, security and device management) depend on a single cloud provider. When that provider has an outage, all of those functions fail together instead of one at a time.

What happened in the November 2026 Microsoft outage?

Problems began at about 16:00 GMT on Thursday, November 12 (11 a.m. Eastern). Outlook was hit hardest across web, desktop and mobile. Copilot was disrupted, and according to TechCrunch, Defender, Intune admin dashboards and some Cloud PCs were affected as well.

Microsoft described a large number of servers becoming “unexpectedly unavailable” and said there was no evidence of malicious activity. By Friday it was rolling back a network change, though it had not said whether that change was the cause. More than 12 hours in, Microsoft reported only “marginal success” restoring service.

74

Countries and territories that logged Outlook, Teams and Copilot problem reports on Downdetector within about an hour (Al Jazeera, Nov 13 2026)

~18 hrs

Approximate downtime before traffic began returning to Microsoft’s services, per network analyst Doug Madory of Kentik (TechCrunch, Nov 13 2026)

This was also not a one-off. It follows a January 2026 Microsoft 365 outage that lasted nearly 10 hours across North America. Two major multi-hour incidents in one year is enough to plan around.

Lesson 1: Is Microsoft 365 a single point of failure for your business?

For most companies with 50 or more staff, yes. Email, Teams, SharePoint and OneDrive files, sign-in, endpoint security and device management very often all come from the same Microsoft tenant. On November 12 several of those failed at the same time, which is very different from losing one tool.

Consolidating on Microsoft 365 is still the right call for most businesses: it is cheaper, more secure and easier to manage than a patchwork of vendors. The trade-off is that you have concentrated your risk, so your continuity planning has to account for it. Map which business functions depend on the tenant and you will usually find the list is longer than expected.

Business functionTypical Microsoft dependencyFallback to have ready
Staff communicationTeams, OutlookSMS or phone tree, conference bridge from a different provider
Customer contactOutlook shared mailboxesPhone lines and a holding message on the website
Files and documentsSharePoint, OneDriveLocally synced copies of critical files on key devices
Device managementIntuneOffline runbook and a list of who has local admin access
Security monitoringDefenderIndependent monitoring (firewall logs, MDR provider)

Lesson 2: How do you reach staff when Teams and Outlook are down?

You need a communication channel that does not run on Microsoft 365, set up before the outage. If your only way to tell 150 people “email is down, here is what to do” is an email or a Teams post, you have no way to tell them.

The simplest version is a current list of staff mobile numbers held outside the tenant, and a group SMS or phone tree that a manager can trigger. Add a conference bridge from a different provider for leadership, and decide in advance who sends the first message and what it says.

Write the first message now, while nothing is broken. Something like: “Microsoft email and Teams are down across the world. This is not a problem with our systems. Use phones for urgent client contact. Next update by [time].” A pre-approved message gets sent in five minutes instead of after a 40-minute discussion.

Lesson 3: Can your IT team still work when the admin portals are down?

Often not as much as you would think. During this outage, administrators reported being unable to reach Intune dashboards. The tools you would use to diagnose and respond were part of the outage.

The fix is unglamorous: keep the critical information somewhere that does not depend on Microsoft. That means an offline or printed copy of your incident runbook, vendor support numbers, your Microsoft tenant ID and support contract details, and emergency (break-glass) admin account procedures. If your runbook lives only in SharePoint, it went down with everything else.

Warning:

Do not “fix” an outage by loosening security. When sign-in is flaky, it is tempting to switch off MFA or relax Conditional Access to get people working. That does not fix a provider outage, and it is easy to forget to switch back on.

Lesson 4: Does a non-cyberattack outage still create security risk?

Yes. Microsoft said there was no sign of malicious activity, but large public outages are a gift to phishing crews. Expect emails and texts pretending to be Microsoft “service restoration” notices, fake password reset links, and calls from people claiming to be Microsoft support.

Tell staff plainly: Microsoft will not email, text or phone them individually about this outage, and IT will not ask for passwords. Also note that with Defender affected, some of your usual security screening may have been degraded for part of the outage. That is a good reason to have monitoring that does not depend on the same vendor, such as firewall logging or an independent managed detection and response service.

Lesson 5: Does your disaster recovery plan cover a cloud provider outage?

Most do not. Traditional disaster recovery plans are written for a fire, a flood, a ransomware attack or a failed server: something that happens to you, where you control the recovery. In a provider outage you control none of the recovery. Your plan is about how the business keeps working while you wait.

Do not count on the SLA to cover the cost either. Microsoft’s Service Level Agreement for Online Services pays out in service credits against your subscription, not compensation for lost productivity or lost sales. The commercial risk of a day without email sits with you.

Here is the short framework we use to add a provider outage to a client’s continuity plan:

List what runs on the tenant: Every business function that stops if Microsoft 365 stops, including the less obvious ones like scanners that email documents, phone systems tied to Teams, and line-of-business apps that sign in with Microsoft accounts.

Set decision points at 2, 8 and 24 hours: Decide now what happens at each. At 2 hours: staff message, switch client contact to phones. At 8 hours: notify key clients, defer deadlines. At 24 hours: leadership call on contractual or regulatory notifications.

Build the out-of-band kit: Staff phone list, SMS or call tree, alternate conference bridge, offline runbook and vendor contacts, all stored outside Microsoft 365.

Assign owners: Name who declares the incident, who sends the staff message, who talks to clients, and who watches the Microsoft service status page for updates.

Run it once a year: A 30-minute tabletop exercise (“it is 11 a.m. and Outlook and Teams are down, what do we do?”) will surface the gaps faster than any document review.

Should you move away from Microsoft 365 after this outage?

For almost every mid-sized business, no. Every major cloud provider has outages, and running a second, parallel email and collaboration platform costs far more than the occasional bad day it would protect you from. Switching vendors swaps one concentration risk for another.

The better investment is resilience around the platform: the out-of-band communication plan, offline runbooks, independent security monitoring, and a tested continuity plan. That is a few days of work, not a migration project, and it pays off the next time any vendor you depend on goes down.

The November 12 outage was Microsoft’s problem to fix, but how long your business stood still was yours. Companies that had a backup way to reach staff, offline runbooks and pre-agreed decision points lost hours of convenience. Companies without them lost a day of work. Use this outage as the reason to close that gap before the next one.

If you want a second set of eyes on how your business would handle the next one, our team can review your Microsoft 365 setup and your backup and disaster recovery plan together, and give you a short list of what to fix first. An incident readiness workshop is also a practical way to run the tabletop exercise above with your leadership team.

Sources

Managed IT Services for Law Firms: An Ontario Guide

Your firm has grown past the point where one IT person, or a partner’s nephew, can keep up. You have 50, 100, maybe 200 people, a document management system nobody fully understands, lawyers working from court and home, and trust account transfers going out every week. Then a client’s general counsel sends over a security questionnaire, and nobody knows how to answer half of it.

This guide covers what managed IT services for law firms should include, which Ontario obligations drive those requirements, and how to tell a provider who understands legal practice from one who just supports offices.

The short answer: managed IT services for a law firm should cover everything a general business needs (help desk, patching, backups, network) plus four things specific to legal practice: protecting privileged client data, securing the money movement around trust accounts, enforcing ethical walls inside your document system, and giving you evidence you can show clients, insurers, and the Law Society. If a provider can’t speak to all four, they are supporting your office, not your practice.

For an Ontario law firm, IT is part of professional responsibility. The Law Society expects technological competence, PIPEDA requires breach records, and LAWPRO’s cybercrime coverage has a ceiling. Managed IT should be scoped around those obligations, not just around keeping computers running.

Managed IT Services for Law Firms

Managed IT services for law firms is an arrangement where an outside provider runs a firm’s technology for a fixed monthly fee: user support, security, backups, cloud systems, and legal applications such as document management and practice management software. Unlike general office IT support, it is built around client confidentiality, trust account security, conflict and ethical wall controls, and records retention.

Why law firm IT is different from general office IT

Law firm IT is different because the data is privileged, the money moves through trust accounts, and the regulator holds individual lawyers responsible for how both are protected. A manufacturer that loses its email for a day loses productivity. A law firm that leaks a client file can face a negligence claim, a Law Society complaint, and the loss of the client relationship in one event.

Three things make legal environments harder to run than they look:

  • Access is matter-based, not department-based. Who can open a file depends on which matters they work on, and conflicts mean some people must be actively blocked from files their own colleagues use every day.
  • The work happens everywhere. Lawyers draft at home, review on phones between court appearances, and share files with opposing counsel and clients outside the firm.
  • Retention rules are long. Closed files have to be kept, findable, and protected for years after the matter ends, which makes backup design a professional obligation, not just a disaster plan.

When we take over IT at a mid-size firm, the pattern we see most often is not a missing firewall. It is permissions that grew by accident: shared folders opened “temporarily” years ago, former associates still in distribution groups, and a document system whose security model nobody has reviewed since it was installed.

What Ontario rules and obligations shape law firm IT

Ontario law firms answer to three sets of expectations that directly affect IT: the Law Society of Ontario’s professional conduct rules, federal privacy law, and the terms of their LAWPRO insurance. None of them hands you a technical checklist, which is exactly why firms need someone who can translate them into controls.

ObligationWhat it says, in plain termsWhat it means for your IT
LSO Rules of Professional Conduct, Chapter 3Lawyers must be competent, and the commentary on competence now covers understanding the technology they use. Confidentiality duties apply to client information wherever it is stored.Partners need to be able to explain, in plain language, how client data is protected. That means documented controls, not “the IT guy handles it.”
PIPEDA breach rulesBreaches that create a real risk of significant harm must be reported to the Privacy Commissioner and affected people, and every breach must be recorded and kept for 24 months.You need logging and monitoring good enough to know a breach happened, what was touched, and when.
LAWPRO cybercrime sublimitThe mandatory policy includes a $250,000 cybercrime sublimit, which LAWPRO itself describes as a modest safety net.A serious incident can exceed that cover. Separate cyber insurance, and the security controls insurers require for it, are part of the plan.
Good to know:

If your firm holds health information (personal injury, medical malpractice, disability claims), Ontario’s PHIPA can also apply to how that information is handled. Ask your provider how they treat health records differently from other client files.

The biggest cyber risk to law firms is the money, not the files

The most expensive attack on an Ontario law firm is usually not ransomware. It is a fraudster who gets into, or convincingly fakes, an email thread and redirects a trust account payment to their own bank account. LAWPRO has repeatedly warned about a rise in schemes that trick lawyers and law clerks into wiring funds out of trust accounts, especially around real estate closings and private mortgages.

These attacks work because they look like normal business. The email comes from a real client’s address (after their mailbox is compromised) or a near-identical domain, the timing matches a closing, and the request is a routine change to payment instructions. Recovery after the wire leaves is rare.

27%

of law firms surveyed reported having experienced a security breach at some point (ABA TechReport 2022, Cybersecurity)

Good managed IT reduces this risk on both sides: technical controls (multi-factor authentication on every mailbox, alerts on suspicious mailbox rules, filtering of look-alike domains) and process controls (a mandatory phone call-back to a number already on file before any change to payment instructions). We go deeper on the email side in our guide to business email compromise.

Check your mailbox rules today. In nearly every email compromise we investigate, the attacker’s first move is a hidden rule that forwards or deletes messages containing words like “wire,” “trust,” or “closing” so the real conversation never reaches the lawyer. Your IT provider should be alerting on new forwarding rules automatically.

What managed IT for a law firm should include

A complete managed IT service for a law firm covers day-to-day support, security, and the legal applications that the firm runs on. Use this table to check a current or proposed agreement. Anything in the right-hand column that isn’t in writing usually isn’t happening.

AreaGeneral office ITLaw firm IT should add
Help deskBusiness-hours supportAfter-hours coverage around filing deadlines and trial prep; support for court and remote work
Identity and accessUser accounts and passwordsMulti-factor authentication everywhere, matter-based permissions, ethical wall enforcement, same-day offboarding
Email securitySpam filteringImpersonation and look-alike domain protection, mailbox rule alerts, encrypted email for client files
MonitoringAntivirusEndpoint detection and response with a 24/7 SOC (security operations centre) that can tell you exactly what an attacker touched
BackupsNightly backupImmutable backups that ransomware can’t delete, tested restores, retention matched to file-retention obligations
ApplicationsMicrosoft 365Document management (iManage, NetDocuments), practice management, billing, e-discovery tools
ReportingTicket countsEvidence for client security questionnaires, cyber insurance renewals, and partner meetings

Offboarding deserves special attention in legal. Associates and clerks move between firms often, and a departing lawyer who keeps access to a shared drive or a synced phone is a confidentiality problem. We explain why the job isn’t finished on the last day in why user offboarding doesn’t end when an employee leaves.

Ethical walls need to exist in your systems, not just in a memo

An ethical wall (a screen that blocks specific people from specific matters because of a conflict) only protects the firm if the technology enforces it. A memo telling a lateral hire not to open certain files does nothing if their account can still open them, search them, and sync them to a laptop.

Done properly, a wall is applied in the document management system, mirrored in any shared drives or Teams sites that hold matter files, and logged so the firm can prove nobody behind the wall accessed the matter. When we review legal environments, the gap is almost always the second step: the document system is locked down, but copies of the same files live in a Teams channel or a personal OneDrive that the wall never reached.

Warning:

Microsoft 365 Copilot and other AI assistants search everything a user is allowed to see. If your permissions are loose, an AI tool will surface walled-off or confidential documents in answers. Fix permissions before turning on AI tools, not after.

How to choose a managed IT provider for a law firm

The right provider can explain your obligations back to you in plain language and show how each one maps to a control they run. Use these steps to evaluate any provider, including your current one.

Ask about trust account fraud first: have them describe how they would stop a redirected wire. If the answer is only “spam filtering,” keep looking. You want both technical alerts and a payment-verification process.

Ask how they enforce ethical walls: they should be able to explain how a wall is applied across the document system, Microsoft 365, and devices, and how access is logged.

Ask who is watching at 2 a.m.: confirm there is a 24/7 SOC with the authority to isolate a compromised device immediately, not just an alert emailed to someone who reads it Monday.

Ask for a restore test: request proof that a closed matter from several years ago can be found and restored. Untested backups are the most common surprise during an incident.

Ask for a sample report: it should be something a managing partner can read and something you could hand to an insurer or a client’s security team.

If your firm already has an internal IT manager, you don’t have to replace them. A co-managed IT arrangement lets your person keep ownership of the legal applications and relationships while a provider covers security monitoring, after-hours support, and the infrastructure work.

Cyber insurance makes the controls non-negotiable

Because LAWPRO’s cybercrime cover stops at $250,000, most mid-size firms carry separate cyber insurance, and those insurers now ask detailed questions about multi-factor authentication, endpoint detection, backups, and incident response plans. A wrong answer on the application can give the insurer grounds to deny a claim later.

Your managed IT provider should help complete those applications accurately and keep the controls in place all year, not just at renewal. We cover the claim side of this in will your cyber insurance actually pay out when you need it?

Managed IT for a law firm should be judged on four questions: can it stop a redirected trust payment, enforce an ethical wall, prove what happened during an incident, and produce evidence for clients and insurers? A provider that answers all four with specifics is supporting your practice, not just your office.

BALANCED+ has supported Ontario businesses since 1994, with a 24/7 SOC and a 15-minute critical response SLA. If you want an outside view of where your firm stands, see how we work with law firms and legal practices, or start with our managed IT services overview.

Sources

Fortinet October 2026 Security Release: What to Do

If you run a FortiGate firewall, FortiManager, FortiAnalyzer, FortiMail or FortiAuthenticator, Fortinet is asking you to upgrade this week, and to treat it as an emergency change rather than routine maintenance. The updates for FortiOS, FortiManager and FortiAnalyzer ship on October 22, 2026; FortiMail and FortiAuthenticator fixes are already out.

This post covers which versions are affected, the order to upgrade in, and what to lock down today if you cannot upgrade yet.

The short answer: Fortinet’s October 2026 security hardening release fixes critical and high-severity flaws in FortiOS, FortiManager, FortiAnalyzer, FortiMail and FortiAuthenticator, found through AI-assisted security testing. Upgrade internet-facing devices first, ideally by October 23. Until then, restrict admin interfaces to trusted IP addresses, keep FortiManager off the internet, and enforce MFA on every admin account.

Fortinet has not published the CVE details yet; they arrive on November 10. That gap is the risk. Attackers can compare old and new firmware to find the flaws, and Fortinet itself warns that AI lets them build working exploits “in hours or days, rather than weeks.” Patch before the details go public.

Security hardening release

A security hardening release is a coordinated set of firmware updates that fixes multiple vulnerabilities across several products at once. Fortinet ships the fixes first and publishes the detailed advisories later, giving customers a head start to patch before attackers learn exactly what was fixed.

What is in Fortinet’s October 2026 security release?

It is a batch of critical and high-severity fixes across five Fortinet products, announced by Fortinet CISO Carl Windsor on October 21, 2026. Fortinet found the issues by adding frontier AI models to its own product security testing, analyzing code paths, protocol handling and configuration logic.

Fortinet has not listed CVE numbers or individual severity scores. Full advisories will be published on the FortiGuard PSIRT page at the next Patch Tuesday, November 10. As of release, Fortinet has not reported any of these flaws being exploited.

As a Fortinet Advanced Partner (and a Fortinet partner since 2003), we read the wording here as unusually direct. Fortinet is asking customers to schedule change windows for October 22 and 23 on internet-facing systems. Vendors do not usually set the calendar for you.

Which Fortinet versions are affected?

Every supported branch of the five products is affected. Find your product and branch below and upgrade to the fixed version or later.

ProductAffectedUpgrade toAvailable
FortiOS 8.08.0.0 to 8.0.18.0.2+Oct 22
FortiOS 7.67.6.0 to 7.6.77.6.8+Oct 22
FortiOS 7.47.4.0 to 7.4.127.4.13+Oct 22
FortiOS 7.27.2.0 to 7.2.137.2.14+Oct 22
FortiManager 8.08.0.0 to 8.0.18.0.2+Oct 22
FortiManager 7.67.6.0 to 7.6.77.6.8+Oct 22
FortiManager 7.47.4.0 to 7.4.117.4.12+Oct 22
FortiManager 7.27.2.0 to 7.2.127.2.13+Oct 22
FortiAnalyzer 8.08.0.0 to 8.0.18.0.2+Oct 22
FortiAnalyzer 7.67.6.0 to 7.6.77.6.8+Oct 22
FortiAnalyzer 7.47.4.0 to 7.4.117.4.12+Oct 22
FortiAnalyzer 7.27.2.0 to 7.2.127.2.13+Oct 22
FortiMail 8.08.0.0 to 8.0.18.0.2+Oct 21
FortiMail 7.67.6.0 to 7.6.67.6.7+Oct 21
FortiMail 7.47.4.0 to 7.4.87.4.9+Oct 21
FortiMail 7.27.2.0 to 7.2.9Move to 7.4 or laterOct 21
FortiAuthenticator 8.08.0.0 to 8.0.38.0.4+Oct 21
FortiAuthenticator 6.66.6.0 to 6.6.106.6.11+Oct 21

Cloud services are mostly handled for you. FortiSASE was updated automatically before release. FortiManager Cloud has the update available but may need a manual update. Public cloud instances are being updated through the cloud providers’ normal release processes, so check yours rather than assume.

Warning:

Running FortiOS 7.0 or older, or FortiMail 7.2? There is no fix on your branch in this release. That puts you on a forced upgrade, and possibly a hardware conversation if your model cannot run a supported version. We covered the trade-offs in the real cost of running outdated FortiGate models.

Why is Fortinet treating this as urgent?

Because once a patch ships, the clock starts for attackers too. Firmware fixes can be reverse-engineered to reveal what was broken, and Fortinet says AI now helps attackers turn that into a working exploit in hours or days. It also warns that AI can chain several lower-severity flaws into one serious attack.

We are seeing the same pattern elsewhere this week. The PHP2Shell vulnerability disclosed on October 21 was turned into a working exploit with AI help, and attackers were testing it before the patch shipped. Firewalls and management consoles are an even more attractive target, because they sit on the edge of the network and hold the keys to everything behind them.

Nov 10

Date Fortinet publishes the full advisories. Every day before then is a head start for defenders (Fortinet, October 2026)

How should you roll out the Fortinet updates?

Inventory, back up, upgrade the internet-facing devices first, then watch the logs. This is the order we follow when we run a coordinated Fortinet upgrade for a client, and it matches Fortinet’s own guidance.

List every device: record every FortiGate, FortiManager, FortiAnalyzer, FortiMail and FortiAuthenticator, its current version, and whether its admin interface can be reached from the internet. Branch-office and lab devices are the ones most often forgotten.

Back up configurations: take a fresh config backup of every device before you touch it, and store it off the device.

Check the upgrade path: FortiOS often needs intermediate versions when you jump several builds. Use Fortinet’s upgrade path tool so a firewall does not come back with a broken config.

Upgrade internet-facing devices first: perimeter FortiGates, VPN gateways, FortiMail and anything with an admin interface exposed. For HA pairs, follow the normal cluster upgrade process to keep traffic flowing.

Review logs before and after: look for admin logins from unfamiliar IP addresses, new admin accounts, or configuration changes nobody approved. Upgrading does not remove an attacker who is already in.

Upgrade FortiManager and FortiAnalyzer before the FortiGates they manage. A management console running an older version than its firewalls can stop pushing policies or receiving logs, and you will find out at the worst moment.

What should you do if you cannot upgrade today?

Shrink who can reach your admin interfaces. Fortinet lists these temporary steps, and stresses they reduce risk but do not replace the upgrade:

  • Limit HTTPS and SSH admin access to trusted IP addresses, or turn admin access off on external interfaces entirely.
  • Make sure FortiManager cannot be reached from the internet.
  • Manage devices out of band, and move management behind a VPN or SASE where you can.
  • Use strong, unique passwords and enforce MFA for every admin account.

If those steps sound familiar, they should. Exposed admin interfaces and reused admin credentials were at the centre of the FortiBleed credential leak, and they are the first things we close on any firewall we take over. Getting them right now protects you against this release and the next one.

What this means for your patching process

A firewall patch that waits for next month’s maintenance window is now a gamble. If your team cannot upgrade every perimeter device within a day or two of a critical release, the gap is in the process, not the people: an incomplete inventory, no tested upgrade path, or no one with time set aside. We wrote about that problem in depth in FortiGate CVEs and the patch management problem.

Upgrade internet-facing Fortinet devices by October 23, management consoles first. Lock down admin access in the meantime, and check logs for unexpected admin activity. Then fix whatever made this upgrade hard, because the next one will be just as urgent.

If you would rather not run this upgrade under pressure, our managed firewall team handles Fortinet upgrades, admin lockdown and log review for organizations across the GTA and BC. We have been a Fortinet partner since 2003, and coordinated releases like this one are routine work for us.

Sources

PHP2Shell Vulnerability: What IT Teams Must Do Now

If your organization runs a website, a customer portal, an intranet, or any web application built on WordPress, Drupal, Magento, Laravel or custom PHP, you have a patching job this week that cannot wait for the next maintenance window. On October 21, 2026, the PHP project shipped emergency fixes for two critical flaws now known as PHP2Shell, and attackers were already testing them before the patches existed.

This post covers what PHP2Shell is, which systems are exposed, how to confirm you are actually patched (the version number alone will not tell you), and what to do today if you cannot patch yet.

The short answer: PHP2Shell (CVE-2026-109618 and CVE-2026-109619) lets an attacker with no login run code on any server that uses PHP to serve web pages. Update to PHP 8.2.35, 8.3.36, 8.4.27 or 8.5.12, restart every PHP worker, and confirm the fix with your host or vendor. If you are on PHP 8.1 or older, you need a vendor backport or an upgrade, because the PHP project no longer ships fixes for those versions.

Treat PHP2Shell as an emergency patch, not a routine one. Exploitation attempts started before disclosure, the flaw triggers before your application code runs, and keeping WordPress or your CMS updated does not protect you. Only a patched PHP runtime does.

PHP2Shell

PHP2Shell is the name for two critical remote code execution vulnerabilities in the PHP runtime, CVE-2026-109618 (out-of-memory corruption) and CVE-2026-109619 (stale global state), each rated 9.2 on CVSS v4.0. They let an unauthenticated attacker run commands or read memory on a web server running PHP, regardless of how secure the application code is.

What is the PHP2Shell vulnerability?

PHP2Shell is a pair of flaws in PHP itself, not in any one application. Both carry a CVSS v4.0 score of 9.2 and can be exploited by a remote attacker who has no account and no password. Because the problem sits in how PHP handles a request before your code runs, application-level logins, plugins and security settings cannot block it.

  • CVE-2026-109618 (out-of-memory corruption): if PHP runs out of memory while it is still setting up a request, the cleanup step later treats half-built data as valid. An attacker can shape that data.
  • CVE-2026-109619 (stale global state): leftover state from one request points to memory that has already been freed, and a later request on the same worker can use it. The PHP advisory lists memory disclosure as a confirmed impact, which means passwords, tokens and API keys from other users’ requests can leak.

The code behind these flaws is old. Researchers traced the affected code path back to PHP 5.4, and the researchers say AI models helped turn the long-known weakness into a working exploit in about a week. That speed is the real story: the gap between “bug exists” and “bug is weaponized” is now measured in days.

1.3M+

Internet-exposed hosts estimated to be potentially vulnerable to PHP2Shell (Silas Cutler, via Tenable, October 2026)

Which PHP versions and servers are affected?

Every PHP branch before the October 21 releases is affected, and so is every common way of running PHP on a web server. If PHP answers web requests on a machine, assume that machine is in scope until you have confirmed otherwise.

PHP branchVulnerableFixed inWhat to do
8.5Before 8.5.128.5.12Update now
8.4Before 8.4.278.4.27Update now
8.3Before 8.3.368.3.36Update now
8.2Before 8.2.358.2.35Update now, then plan to move off 8.2 (end of life December 31, 2026)
7.4 to 8.1AllNo official releaseGet a vendor backport or upgrade to a supported branch
5.4 to 7.3AllNoneUpgrade or isolate the system

On the server side, Datadog Security Labs lists Apache with mod_php, PHP-FPM, php-cgi, FrankenPHP and LiteSpeed as in scope. PHP rates mod_php as the highest risk, because a single unauthenticated request can trigger the attack before any application code runs. Researchers also confirmed pre-authentication code execution against specific versions of WordPress, Drupal, Joomla and Magento.

Warning:

Updating WordPress, Drupal or your plugins does not fix PHP2Shell. WordPress.org has said no WordPress update is required or planned. The fix lives in the PHP runtime on the server.

Is PHP2Shell being exploited right now?

Yes. Exploitation attempts began before the patch was public, and they increased on release day. As of October 21, no confirmed break-ins had been publicly reported, but that tends to lag the attacks by weeks.

  • October 17: Amazon Threat Intelligence saw an attempt against its honeypot, four days before disclosure. Amazon recommends starting investigations from this date.
  • October 20: a working proof of concept video was mistakenly posted, and the PHP project moved its release up a day.
  • October 21: Cloudflare reported early attacks and pushed emergency firewall rules; watchTowr reported “active exploitation attempts” against both CVEs; PHP released the fixes at 14:00 UTC.

Canadian organizations felt it on day one. BambooHR took its service offline in the US, Canada and Ireland as a precaution, interrupting payroll for its customers. That is worth sitting with: even if your own servers are clean, the SaaS tools your HR, finance and operations teams depend on may be running PHP too. If you want the background on why pre-patch attacks like this are so dangerous, our explainer on zero-day exploits covers it.

How do you check if you are patched?

Check the PHP version your web server actually runs, then confirm the fix with whoever supplies that PHP build. The version string can mislead you in both directions, so a version number on its own is not proof.

This is the step we see trip teams up most. The PHP version shown on the command line is often not the one the web server uses, and many servers run several versions side by side. Linux distributions and control panels such as cPanel often apply the fix without changing the displayed version number. A server showing PHP 7.4 may be patched by its vendor; a server showing 8.3 may still be on an unpatched build in a forgotten container.

When we inventory PHP for a client, we look in four places, not one: web servers, containers and images, third-party hosted sites (the marketing site, careers portal, event microsites), and vendor appliances with a web console. The marketing website on an agency’s hosting account is the one most often missed, because IT never set it up.

  • WordPress sites: in the dashboard, go to Tools, then Site Health, then the Info tab, and open the Server section. Then ask your host in writing whether the October 21 fix is applied.
  • Linux packages: check the package changelog for CVE-2026-109618 and CVE-2026-109619, not the version number.
  • Containers: rebuild images from patched base images and redeploy. A patched host does not patch a container that bundles its own PHP.
  • Vulnerability scanners: Tenable has published Nessus plugin 369483 for this issue; most major scanners have added checks.

What should IT teams do in the next 48 hours?

Find every PHP system, patch the internet-facing ones first, restart the workers, and look back to October 17 for signs of compromise. This is the order we work in with clients, because it closes the most exposure in the least time.

Build the list: record every system that runs PHP, who owns it, where its PHP comes from (distribution package, control panel, container image, host) and how it gets updated. Include sites hosted by agencies and vendors.

Patch internet-facing systems first: apply the upstream or vendor update on anything reachable from the internet, starting with Apache mod_php servers. Internal-only systems come second.

Restart every worker: a patched package does nothing until the old PHP processes are gone. Restart PHP-FPM pools and Apache, and redeploy containers.

Get written confirmation from hosts and vendors: for anything you do not manage directly, ask whether the October 21 fix is applied and when. Keep the replies.

Hunt back to October 17: review logs on exposed systems for the warning signs listed below, and rotate any secrets (database passwords, API keys, tokens) stored on servers that were exposed and unpatched.

Rotating secrets is the step most teams skip, and it matters here. Because CVE-2026-109619 can leak memory without running any code, an attacker may have read credentials without leaving the usual traces. The same patch-under-pressure problem shows up with firewalls; we wrote about it in FortiGate CVEs and the patch management problem.

What if you cannot patch PHP yet?

Apply the interim settings, put a web application firewall in front of the site, and isolate anything you cannot protect. None of these is a fix. The PHP security team is clear that only updating PHP fully closes the hole.

  • For CVE-2026-109619: set session.upload_progress.enabled=0 (and on PHP 8.5, fatal_error_backtraces=0), then restart all workers. WordPress does not use upload progress, so a typical site should not notice.
  • For CVE-2026-109618: set memory_limit=-1 at the administrator level so applications cannot override it, keep post_max_size low, and enforce request-size limits at the web server or proxy.
  • Web application firewall: Cloudflare has deployed rules for known attack patterns to all customers, including free plans. Set managed rules to block, not just log. Attackers have already changed payloads to get around them.
  • Isolation: CERT-EU recommends taking internet-facing applications off public networks until a fix is applied and verified.
Good to know:

Running PHP 8.1 or older? This is the push to upgrade. Those versions get no official fixes, and PHP 8.2 itself reaches end of life on December 31, 2026. Plan the move to 8.3 or newer now, test it on a staging copy, and you will not be in the same position next time.

What are the signs your server was already hit?

Look for unusual request patterns, early memory errors, crashing workers and, most of all, a web process starting a shell. A successful attack does not necessarily crash anything or change the page, so a site that “looks fine” is not evidence of anything.

  • POST requests with an unusually long field name (one documented example was about 3.5 MB) or binary data in a field with no name
  • Errors like Allowed memory size ... exhausted with the location Unknown on line 0, meaning the failure happened before any script ran
  • Repeated HTTP 500 responses, segmentation faults or unexplained PHP worker restarts
  • Unusually large PHPSESSID cookies
  • A web server process (for example apache2 or php-fpm) spawning sh or bash, which is the most direct evidence of exploitation

That last signal is why endpoint and server monitoring matters more than log review alone. A managed detection and response service watching process behaviour on your servers will flag a web worker opening a shell within minutes, whether or not anyone knew the vulnerability existed yet.

Does PHP2Shell trigger PIPEDA breach reporting?

It can. If an exposed server held personal information and you find evidence it was accessed, PIPEDA requires you to assess whether the breach creates a “real risk of significant harm.” If it does, you must report it to the Office of the Privacy Commissioner of Canada and notify affected individuals as soon as feasible.

Two details catch Canadian organizations out. First, you must keep a record of every breach for two years, even ones that fall below the reporting threshold. Second, the memory-disclosure side of CVE-2026-109619 means “no code ran” is not the same as “no data left.” If you cannot rule out exposure on a server handling customer, patient or employee data, document your assessment now, while the facts are fresh. Our guide to building an incident response plan walks through how to structure that work.

What this means for your patching process

PHP2Shell is a test of whether your organization knows what it runs. The teams that close this out in a day are the ones with a current inventory of every web-facing system, a named owner for each, and an agreed emergency patch path that does not wait for a monthly window.

Expect more of these. The researchers behind PHP2Shell say AI cut weeks of exploit work down to days, and Fortinet gave its customers the same warning this week about its own security release. A 30-day patch cycle for internet-facing systems was already risky; it no longer matches how fast attackers move.

Patch PHP to 8.2.35, 8.3.36, 8.4.27 or 8.5.12 (or get a confirmed vendor backport), restart every worker, check logs back to October 17, and rotate secrets on any server that was exposed. Then use this week to fix the inventory gap that made it hard.

If you are not sure how many PHP systems you have, or who is responsible for patching the ones your vendors host, that is exactly the kind of gap our cybersecurity team closes. We can help you inventory exposed systems, confirm patch status, and check for signs of compromise, so you have a clear answer instead of a guess.

Sources

Beyond the Sender: Following the Phishing Attack Path

A reported phishing email may look like a single-message problem. A proper investigation looks beyond the sender to determine where the message leads, how far it reached, whether anyone interacted with it, and what actually needs to be contained.

Security awareness training has made many employees more familiar with the warning signs of phishing. A suspicious sender, an unexpected request, or an unusual link may be enough for someone to stop and report the message to IT. That report is important, but for the security team it is only the beginning of the investigation.

A phishing email rarely exists as just a sender and a message. Behind it may be a chain of redirects, separate destination domains, additional recipients, and evidence of user interaction. Looking only at the sender address can answer one question while leaving several more important ones unresolved: Where does the message actually lead? Who else received it? Did anyone interact with it? And what should actually be contained?

By the numbers

28%

of breaches investigated by Microsoft Incident Response were initiated through phishing or social engineering. (Microsoft Digital Defense Report 2025)

$2.77B

in reported 2024 losses associated with Business Email Compromise complaints. (FBI Internet Crime Complaint Center)

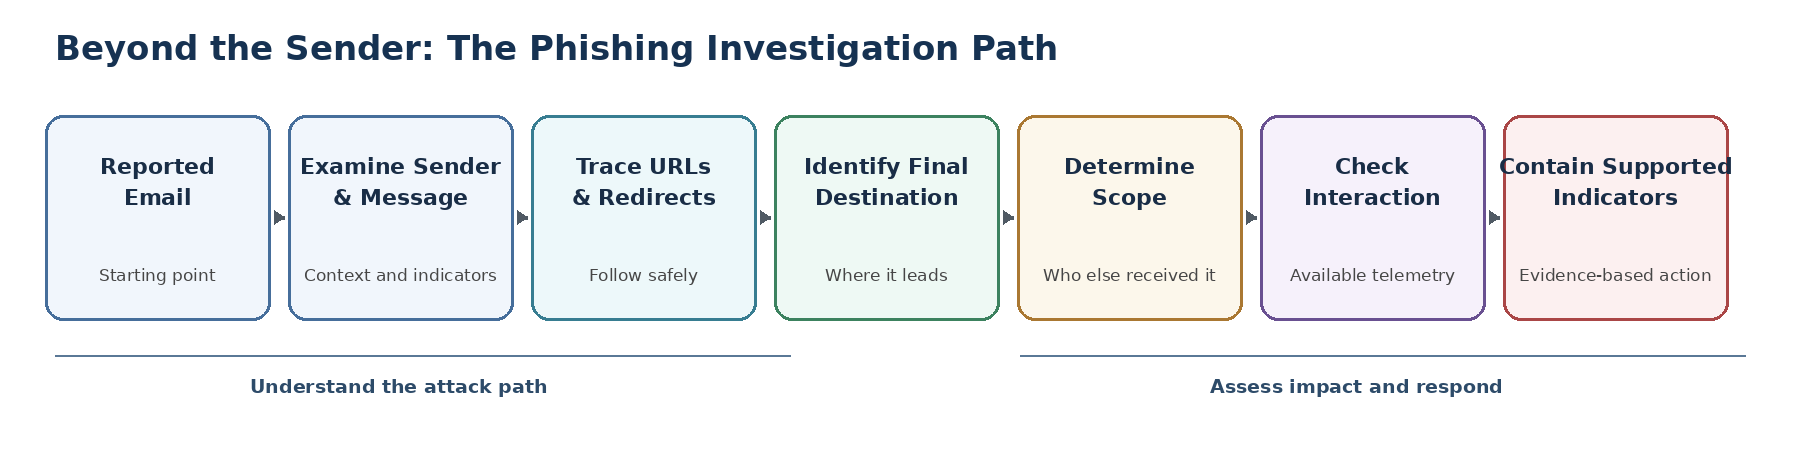
Seven-step phishing investigation path: reported email, examine sender and message, trace URLs and redirects, identify final destination, determine scope, check interaction, contain supported indicators
Figure 1. A reported email is the starting point. Investigation follows the message through scope, interaction, and evidence-based containment.

The Sender Is Only the Starting Point

The sender address still matters. It can help establish whether a message came from an expected source, whether the sending domain is suspicious, and whether the same sender appears elsewhere in the environment. But it is only one indicator. Attackers can spoof identities, abuse legitimate services, rotate sending accounts, or use one domain to deliver a message that ultimately sends the recipient somewhere completely different.

This is why a reported message should be treated as an entry point into the investigation rather than the entire incident. The objective is not simply to decide whether the From address looks suspicious. It is to reconstruct enough of the activity to understand the threat and respond proportionately.

Follow Where the Message Actually Leads

In several phishing investigations, one of the most useful questions has been simple: where would the user actually end up? The URL displayed in a message may not be the final destination. A link can pass through a legitimate service, tracking mechanism, or redirect before reaching infrastructure controlled or abused by the attacker.

That makes URL analysis more than a reputation check on the first domain we see. The redirect chain and final destination can reveal infrastructure that is more relevant to containment than the visible sender itself. This analysis should be performed safely using appropriate security tooling or an isolated analysis environment, not by casually opening suspicious links from a production workstation.

The destination also needs context. Domain reputation, registration information, security detections, message characteristics, and other threat intelligence can all contribute evidence. No single result should become the verdict. A newly registered domain is not automatically malicious, and a clean reputation result does not prove a site is safe. The stronger conclusion comes from correlating multiple indicators with what the message is actually trying to make the recipient do.

Good to know:

Good to know: The domain visible in an email is not necessarily the final destination. Redirects can move a user through multiple services or domains before reaching the actual landing page. Investigating that chain can reveal indicators that are not obvious from the original message.

One Report May Reveal a Wider Campaign

The employee who reports a phishing email sees one message. The investigator needs to determine whether that message is isolated or part of something larger.

Message tracing and email security telemetry can show whether similar messages reached other recipients, when they were delivered, and whether related activity exists. This changes the question from “Is this email suspicious?” to “What is the scope of this activity?” Microsoft Defender for Office 365, for example, correlates campaign information such as sending sources, recipients, payload URLs, delivery state, and URL clicks. Trend Micro email security tooling similarly exposes suspicious URLs, related messages, and recent recipients.

That scope matters operationally. Blocking one sender may address the message that was reported, but it may not address copies already delivered to other users or a malicious destination being reused through different messages.

Establishing Delivery Does Not Establish Impact

Finding additional recipients establishes the reach of a message, but it does not by itself establish compromise. Delivery, link interaction, credential submission, and malicious execution represent different levels of potential impact, and each requires its own supporting evidence.

Where the security platform provides the visibility, investigators can review click or interaction telemetry and correlate it with the affected messages. The wording of the conclusion matters as well. If no interaction appears in the available telemetry, the defensible finding is that no interaction was observed in that telemetry, not an absolute claim that no user could have interacted with the message.

If the evidence indicates credential submission, malware execution, or another form of compromise, the investigation should expand beyond email. That may require reviewing authentication activity, sessions, endpoint telemetry, mailbox changes, or other evidence appropriate to the incident.

Important:

Important: A delivered message, a clicked link, and a compromised account are different findings. Each requires different evidence and can lead to a different response.

Contain What the Evidence Supports

Containment should follow the evidence, and it does not always mean blocking everything associated with a message. Depending on the investigation, the appropriate action might include blocking a confirmed malicious sender, URL, domain, or related infrastructure; removing delivered messages; or adding confirmed indicators to the organization’s security controls.

Containment can also begin before every investigative question has been answered when the evidence is strong enough to justify reducing exposure. The investigation then continues to determine whether the scope or response needs to expand. At the same time, overly broad blocking can disrupt legitimate business communication, so the response should remain proportional to what the evidence supports.

Good to know:

Good to know: More blocking is not always better. Blocking an entire legitimate domain because one sender or URL is suspicious can disrupt business communications. Effective containment targets the indicators the investigation actually supports.

A phishing report may begin with one suspicious email, but a sound investigation looks beyond the sender. Following the attack path helps determine where the message leads, how broadly it was delivered, whether users interacted with it, and which indicators actually need to be contained.

What Organizations Can Take From This

Organizations should make it easy for employees to report suspicious messages, but the process should not end with the report. Effective response also depends on having enough visibility to determine who received the message, investigate the infrastructure behind it, review available interaction telemetry, and act on confirmed malicious indicators. That requires the right email security controls, logging, response procedures, and technical expertise to turn a user report into an informed security decision.

Questions your organization should be able to answer

  • When an employee reports phishing, who investigates it?
  • Can you determine whether other employees received the same message?
  • Can you safely analyze where suspicious links ultimately lead?
  • Can you determine whether available telemetry shows user interaction?
  • Can you remove malicious messages already delivered to other mailboxes?
  • Can you block confirmed indicators without unnecessarily disrupting legitimate communication?
  • If compromise is suspected, is there a defined path to broader incident response?

The Bottom Line

For organizations, the difference between receiving a phishing report and responding effectively is the capability behind that report. Someone still needs to investigate the message, determine its scope, assess potential interaction, contain confirmed threats, and recognize when the evidence requires a broader incident response.

A user reporting a suspicious email may be the first line of defense. What happens next determines how effective that defense actually is. The investigative work behind the report is what turns one suspicious message into an evidence-based security response that can protect the wider organization.

Sources

Why User Offboarding Doesn’t End When an Employee Leaves

Disabling a user account is often treated as the last step in an employee’s departure. It is really the first. Effective offboarding keeps going after the account goes dark, through Active Directory reviews, licence checks, and access audits that catch what the original checklist missed.

This article covers what a complete offboarding process looks like, why the work continues long after someone’s last day, and how regular audits keep an environment organized and accurate.

Offboarding does not end when an account is disabled because accounts, licences, group memberships, and mailboxes all outlive the person they were created for. A user can be blocked from signing in while their Microsoft 365 licence stays assigned, their mailbox stays live with no owner, and their security group memberships stay in place. Regular Active Directory and Microsoft 365 audits are what catch those leftovers and turn offboarding from a one-day task into a maintained process.

Disabling the account is step one, not the finish line. The environments that stay clean are the ones where account reviews, licence checks, and group audits happen on a schedule, not during an occasional cleanup project.

User offboarding

User offboarding is the full set of IT tasks that follow an employee’s departure: disabling accounts, blocking sign-in, reclaiming or reassigning licences, reviewing group memberships, handling the mailbox, updating distribution lists, recovering devices, and documenting all of it. It also includes the ongoing reviews that confirm each of those steps actually stuck.

Why does user offboarding matter?

Every organization has departures. Retirements, role changes, contract endings, and resignations all land on IT, and IT decides whether the transition is clean or whether it leaves debris behind.

Offboarding is much more than removing access. Email accounts, licences, shared resources, group memberships, and company devices all need to be reviewed and handled.

Without a consistent process, organizations accumulate inactive accounts, outdated permissions, and unused resources. None of it breaks anything on the day it happens, which is exactly why it builds up. A year later, nobody can tell which accounts are real.

What happens when an employee leaves?

Most IT teams work from a checklist. Depending on the organization, the common tasks are:

  • Disabling Active Directory and Microsoft 365 accounts
  • Blocking sign-in access
  • Removing or reassigning software licences
  • Reviewing security group memberships
  • Managing email and mailbox access
  • Updating distribution lists
  • Securing company-owned devices
  • Documenting what was done

These steps protect business continuity and close off access to company systems. For the mechanics of the Microsoft 365 side, we walk through it step by step in how to decommission accounts in Microsoft 365.

For most organizations, though, that checklist is only the first phase.

Why doesn’t offboarding end with disabling an account?

In an ideal environment, every account, permission, and licence would be handled the day someone leaves. In practice, organizations are always changing, and details get missed.

An account gets disabled correctly, but the licence stays assigned. A mailbox is still sitting there months later with no owner. A security group still lists members who no longer need access.

As environments grow, these small gaps get harder to spot without a periodic review. That is why many IT teams run Active Directory and Microsoft 365 audits on a set cadence. The audits confirm the offboarding steps were completed and surface anything that needs a second look.

Important:

The point of an audit is not to delete things. It is to understand what exists, decide whether it is still needed, and make sure it is being managed by someone.

How do Active Directory audits uncover forgotten accounts?

Active Directory is the central record of who is who for most organizations. Over time it collects entries as people join, leave, transfer between departments, and come in for short projects.

A regular audit surfaces:

  • Inactive user accounts
  • Disabled accounts that need a decision
  • Duplicate user records
  • Test accounts nobody removed
  • Legacy service accounts
  • Outdated department information
  • Inaccurate contact details

Most of these started as legitimate business needs. They just stayed in the environment long after the reason for them expired.

Reviewing account activity and status on a schedule keeps the directory cleaner and the data more accurate. On the Microsoft 365 side, Entra ID reports on inactive user accounts using last sign-in activity, which gives you a defensible starting list rather than guesswork. A well-maintained directory also makes troubleshooting easier, because administrators can trust what they are looking at.

Why should Microsoft 365 licences be reviewed?

Licensing is one of the most common findings in an audit, and the easiest one to put a dollar figure on.

Licences get assigned during onboarding. They do not always come off when they are no longer needed. Staffing changes, role transitions, and short-term projects all leave assignments behind.

Common examples:

  • Departed employees who still hold an assigned licence
  • Duplicate user accounts, each with its own licence
  • Temporary project users
  • Accounts sitting on premium licensing they no longer need

Reviewing assignments lets you reclaim unused licences, cut unnecessary cost, see what you are actually paying for, and simplify the next round of onboarding. In many cases the licences recovered in an audit cover the next few hires, so no new purchase is needed at all.

Run the licence review a week or two before your renewal date, not after. Seat counts are easiest to adjust at renewal, and a review done at the wrong point in the term means you keep paying for what you just found.

What else should IT teams look for?

User accounts and licensing are only part of a healthy environment. A complete review also covers the shared resources that quietly outlive their owners.

Security groups

People change roles, departments, and responsibilities. Reviewing group membership keeps access lined up with what someone actually does today, rather than what they did three roles ago.

Shared mailboxes

Shared mailboxes routinely outlive the person who set them up. A periodic review confirms the mailbox is still needed and that the right people have access to it.

Distribution lists

Outdated distribution lists cause missed communication and confusion. Verifying membership is a small job that prevents a lot of small problems.

Service accounts

Applications rely on service accounts for automated tasks and integrations. Auditing them keeps each one documented, owned, and still necessary.

User information

Accurate job titles, departments, contact details, and manager assignments make reporting, administration, and day to day user management work properly across the organization.

How do you build a repeatable offboarding process?

The environments that stay clean do not rely on occasional cleanup projects. They fold the review into normal IT operations, so the work is small and constant instead of large and rare.

Document the checklist: Write the offboarding steps down and use the same list every time, so completion does not depend on who handled it.

Review inactive accounts on a schedule: Pull accounts with no recent sign-in activity and decide on each one rather than leaving them in place by default.

Audit licence assignments: Match assigned licences against active users, and time the review to your renewal date.

Validate group memberships: Confirm security groups reflect current roles, not historical ones.

Confirm shared mailbox ownership: Every shared mailbox and distribution list should have a named owner who still works there.

Keep user records current: Update titles, departments, and manager assignments as organizational changes happen, not once a year.

Document as you go: Record what was reviewed and what was decided, so the next audit starts from a known position.

Small, consistent reviews beat large cleanup efforts run every few years. When maintenance is routine, issues get caught while they are still minor.

The bottom line

User offboarding does not end when an employee leaves. Disabling the account is an important first step, but keeping a healthy environment takes ongoing review and verification.

Active Directory audits, Microsoft 365 licence reviews, and access checks surface inactive accounts, reclaim unused resources, and keep user information accurate. That makes administration simpler and the environment easier to work in for everyone.

Key takeaways

  • Effective offboarding goes well beyond disabling user accounts.
  • Active Directory audits surface inactive and outdated accounts.
  • Microsoft 365 licence reviews recover unused seats and cut cost.
  • Security groups, shared mailboxes, and distribution lists need regular review.
  • Ongoing maintenance keeps environments organized, accurate, and easier to manage.

For IT support teams, this kind of proactive maintenance happens quietly in the background. It is also one of the most valuable things you can do to keep systems running smoothly as an organization grows. If account and licence hygiene keeps slipping down your list, our Microsoft 365 management and identity and access management teams run these reviews as part of ongoing service. Get in touch if you want a second set of eyes on your directory.

Sources

Copilot Adoption: Why Most Licenses Go Unused

Most businesses we work with in the GTA already pay for Microsoft 365 Copilot. Far fewer can say their team actually uses it. The license shows up on the Microsoft invoice every month, the icon sits in the Office ribbon, and for most employees it stays exactly where it started: unopened.

This post explains why Copilot adoption fails even when the rollout looks technically complete, what separates the businesses getting real value from it, and how to build a training plan that actually changes how your team works.

Copilot adoption fails almost every time it is treated as a licensing decision instead of a change management project. Turning on Copilot for a tenant takes an afternoon. Getting a finance team, a project manager, and a front desk coordinator to change how they draft emails, build reports, and run meetings takes structured training, manager reinforcement, and use cases specific to their actual job, not a generic “here’s what Copilot can do” webinar.

Buying Copilot licenses and training your team to use Copilot are two separate projects. Most businesses only budget for the first one, then wonder why adoption numbers are flat six months later.

Copilot Adoption

Copilot adoption is the percentage of employees with a provisioned Microsoft 365 Copilot license who use it regularly as part of their actual workflow, as opposed to employees who have access but rarely or never open it. High license counts do not indicate high adoption. A business can have 100% of staff licensed and still see adoption in the 30-40% range if training and workflow integration never happened.

Why Do Most Copilot Licenses Go Unused?

Because employees were given a tool, not a reason to change a habit. Copilot only saves time once someone has learned to trust it with a real task, and that trust is built through repetition with guidance, not a single onboarding email. Without that step, Copilot competes with a workflow the employee already knows works, and the familiar workflow wins.

35.8%

Share of employees with Microsoft Copilot access who use it regularly, compared to 83.1% for ChatGPT among U.S. workers with workplace access (Recon Analytics, U.S. AI Survey, January 2026)

That 47-point gap between Copilot and ChatGPT is not a product quality problem. Copilot is deeply integrated into Word, Outlook, Teams, and Excel, tools employees already use every day, which should make adoption easier than a standalone chatbot. The gap is a training and rollout problem. Microsoft’s own 2026 Work Trend Index, based on a survey of 20,000 knowledge workers across 10 markets, found that organizational factors, culture, manager support, and structured rollout, account for more than twice the reported impact on AI success as individual factors (67% versus 32%).

Good to know:

Among employees who do use AI tools like Copilot regularly, 66% report spending more time on high-value work and 58% say they are producing work they could not have produced a year ago, according to the same Work Trend Index. The gap between those results and a 35.8% conversion rate is almost entirely a training gap, not a capability gap.

What Does Good Copilot Training Actually Look Like?

Good Copilot training is role-specific, hands-on, and tied to real documents the employee already works with, not a generic feature tour. A 45-minute all-hands demo showing Copilot summarize a sample report tells an accounts payable clerk almost nothing about how to use it for their actual job. Effective training walks small groups through Copilot inside the documents, inboxes, and meetings they touch every day.

  • Role-based sessions, not company-wide webinars. Finance, project management, and admin staff use Copilot completely differently. Train them separately with prompts built around their actual documents.
  • A short list of approved starting prompts per role, not a 50-item cheat sheet nobody reads. Three or four prompts an employee can copy and adapt on day one beat an exhaustive reference guide.
  • Manager reinforcement in the first 30 days. Adoption that isn’t checked in on by a manager within the first month tends to fall back to zero. This was the single strongest factor in Microsoft’s own research.
  • A clear data governance conversation before rollout, so employees know what Copilot can and cannot see across SharePoint and Teams. Uncertainty about oversharing is one of the quieter reasons cautious employees avoid using it at all.

Run your Copilot training in the same week you tighten SharePoint and Teams sharing permissions. Employees who are worried Copilot might surface a document it shouldn’t will quietly avoid the tool rather than raise the concern. Fixing oversharing first removes that hesitation before it ever becomes a habit. See our guide to SharePoint oversharing risk for the fix.

Where We See Copilot Rollouts Break Down in GTA Businesses

When we audit Microsoft 365 tenants for mid-market clients, the pattern repeats often enough to call it the default outcome, not the exception. Copilot gets licensed for the whole company at once, usually as part of an upgrade to a higher M365 tier, IT confirms the license activated, and the project gets marked complete. Nobody schedules the second half of the project: teaching people to use it.

Nine times out of ten, the businesses seeing real adoption are the ones where a manager, not IT, championed specific use cases inside their own team, a sales manager building a Copilot-drafted follow-up email routine, an operations lead using it to turn meeting notes into action items. IT can configure the tenant correctly and still see adoption stall if nobody owns the habit-building on the business side.

We also see a smaller but costly mistake: businesses licensing Copilot for every employee on day one instead of piloting with a smaller group first. A 20-person pilot with structured training and a feedback loop almost always produces a stronger business case, and a cleaner rollout plan, than licensing all 150 staff and hoping usage catches on organically.

DIY Copilot Rollout vs. Managed Copilot Training: What’s the Difference?

A DIY rollout relies on internal IT to license Copilot and point employees to Microsoft’s documentation. A managed rollout pairs the technical configuration with role-based training, governance review, and adoption tracking, so the license investment actually turns into changed behaviour.

ComponentTypical DIY RolloutManaged Copilot Rollout
License activationTurned on tenant-wide at oncePiloted with one team, then expanded
TrainingOne all-hands webinar or noneRole-based sessions with real documents
Data governanceReviewed after a problem surfacesSharePoint and Teams permissions audited first
Manager involvementLeft to individual managers to figure outBuilt into the 30-day rollout plan
Adoption trackingRarely measured after launchUsage reviewed monthly against a baseline

How Do You Build a Copilot Adoption Plan That Sticks?

A Copilot adoption plan that sticks starts with a small pilot group, sets a specific usage target, trains by role instead of company-wide, and checks progress against that target every 30 days for the first quarter. Skipping any one of these steps is usually where adoption stalls.

Audit before you license everyone: Review your current Microsoft 365 tenant and identify which teams have the clearest, fastest Copilot use cases. Sales, project management, and executive assistants are usually the quickest wins.

Pilot with 15-25 employees first: License a focused group, not the whole company. A pilot gives you a real usage baseline and a group of internal advocates before the broader rollout.

Train by role, inside real documents: Run short, hands-on sessions using each team’s actual reports, inboxes, and meeting formats. Skip the generic feature tour.

Set a usage target and review it monthly: Track weekly active Copilot usage against a baseline for the first 90 days. If a team’s usage is flat after 30 days, that is a training gap to fix, not a tool to abandon.

Expand license by license, not company-wide: Add the next team once the pilot group’s usage holds steady, so training capacity keeps pace with license growth instead of falling behind it.

Copilot adoption is a training and change management outcome, not a licensing outcome. Businesses that pilot with a small group, train by role, and check usage against a target for the first 90 days consistently see higher adoption than businesses that license everyone at once and hope it catches on.

If your business is sitting on Copilot licenses nobody is using, the fix usually isn’t more licenses or a different AI tool, it’s a structured rollout. Our Microsoft 365 Management service audits your tenant, tightens the SharePoint and Teams governance that quietly discourages adoption, and builds the role-based training plan to get your team actually using what you’re already paying for. For ready-to-use prompts once training is underway, our Copilot prompts guide is a good next stop for your team.

Sources

Managed IT Services for Small Business: What’s Included (and What to Watch For)

Most small businesses do not have an IT department. They have a person: an office manager who resets passwords, an owner who picks the software, and an hourly technician who shows up when something breaks. That arrangement works until the day it doesn’t, and that day usually involves a server, a deadline, and a large invoice.

This guide explains what managed IT services for small business actually include, what providers commonly leave out of the base price, and how to evaluate an MSP in the Toronto and GTA market before you sign anything.

Managed IT services for small business bundle day-to-day IT support, 24/7 monitoring, patch management, cybersecurity basics, backup, and vendor management into one flat monthly fee per user. Instead of paying a technician to fix failures after they happen, you pay an MSP (managed service provider) to prevent them. For most Canadian small businesses, a fully managed agreement runs roughly $100 to $200 per user per month depending on scope.

A managed IT agreement should cover support, monitoring, patching, security, and backup as standard. If one quote is noticeably cheaper than the others, the difference is almost always hiding in the exclusions, so read the scope document more carefully than the price.

Managed IT Services

Managed IT services are the ongoing, proactive management of a company’s technology (help desk, devices, networks, security, and data) by an outside provider called an MSP, delivered under a fixed monthly contract with defined response times, rather than billed hourly after something breaks.

What’s Included in Managed IT Services for Small Business?

A complete managed IT agreement covers eight core areas: help desk support, monitoring, patch management, endpoint protection, email and Microsoft 365 administration, backup, network management, and vendor management. If a quote is missing any of these, ask why before you compare prices.

  • Help desk and remote support: a real help desk your staff can call or email when Outlook won’t open or the printer disappears. Confirm the hours and how “unlimited” is defined.
  • 24/7 monitoring and alerting: agents on every server and workstation that flag failing drives, full disks, and offline services before users notice.
  • Patch management: scheduled operating system and application updates, tested and deployed on a cadence, not “whenever Windows gets around to it.”
  • Endpoint protection basics: managed antivirus or EDR on every device, plus email filtering. This is the security floor, not the ceiling.
  • Microsoft 365 and email management: licence administration, user setup, mailbox and Teams management, and sensible security defaults like MFA enforcement.
  • Backup and disaster recovery: automated, monitored backups of servers and Microsoft 365 data, with documented restore testing.
  • Network and Wi-Fi management: firewalls, switches, and access points configured, documented, and kept on current firmware.
  • Vendor management: the MSP deals with your internet provider, phone vendor, and line-of-business software support so your staff don’t sit on hold.

When we onboard a new client, the first 30 days are mostly discovery. In a typical 25-person company we find unmanaged laptops, a dozen software subscriptions nobody remembers buying, and at least one former employee who still has access to something. The most common security gap we see is offboarding, not the firewall.

Ask every provider for their service catalogue in writing, with inclusions and exclusions listed line by line. A provider that can’t produce one in 24 hours doesn’t have a defined service, which means you’ll be negotiating scope during every incident.

What’s Usually Not Included (and What to Watch For)?

Most managed IT contracts exclude project work, hardware and licensing costs, advanced cybersecurity, and after-hours emergencies beyond the SLA. None of these exclusions are unfair, but each one needs to be priced and understood before you sign.

  • Projects: server migrations, office moves, and cloud migrations are quoted separately. Ask for typical project rates up front.
  • Hardware and licensing: laptops, firewalls, and Microsoft 365 licences are billed as pass-through costs on top of the monthly fee.
  • Advanced security: managed detection and response, SIEM, penetration testing, and compliance work are usually add-on security services. Basic antivirus is standard; a monitored 24/7 security operation is not.
  • Onboarding fees: many MSPs charge one to two months of fees to document and stabilize your environment. Reasonable, but it should be stated, not discovered.
  • After-hours work: check whether evenings and weekends are covered or billed at a premium.
Warning:

Watch for “all-in” pricing that quietly caps support hours or bills “out of scope” labour at emergency rates. The surcharges never appear in the proposal; they appear on month-three invoices. Ask a reference client whether their invoices match their quote.

On security specifically: treat the split between “IT” and “security” with suspicion. The provider managing your devices is best positioned to secure them, which is why we argue managed IT and cybersecurity should be combined rather than bought from two vendors who blame each other during an incident.

How Is Managed IT Different From Break-Fix Support?

Break-fix means you call a technician after something fails and pay by the hour. Managed IT means a provider is paid a flat fee to keep things from failing in the first place. The difference is not just billing; it is who carries the incentive. A break-fix technician earns more when your systems break. An MSP earns more when they don’t.

FactorBreak-FixManaged IT
BillingHourly, unpredictableFlat monthly fee per user
IncentivePaid when things breakPaid to prevent breakage
Response timeWhenever the tech is freeContractual SLA
SecurityRarely addressedPatching, EDR, MFA as standard
BudgetingSpiky, surprise invoicesPredictable line item
Best forUnder ~5 staff, low IT dependenceAny business that stops when IT stops

The security column matters more than most owners assume. Small businesses are targeted precisely because they patch late and lack monitoring, and breach costs have kept climbing.

USD $4.4M

Global average cost of a data breach, per IBM’s Cost of a Data Breach Report 2025. Prevention through patching, MFA, and monitoring costs a fraction of recovery.

You don’t need an enterprise security budget to avoid being the easy target. The Canadian Centre for Cyber Security’s baseline controls for small and medium organizations map almost one-to-one onto what a competent MSP does as standard: patching, MFA, backups, and endpoint protection.

What Do Managed IT Services Cost for a Small Business?

Expect roughly $100 to $200 CAD per user per month for a fully managed agreement in the Ontario market, with security-heavy stacks at the top of that range. For a 20-person company, that is $2,000 to $4,000 a month, well below the cost of a single full-time hire: Government of Canada Job Bank wage data puts experienced systems administrators in Ontario at $80,000 a year or more before benefits, and one person can’t cover 24/7 anyway.

Price alone tells you very little; scope tells you everything. We break down the tiers, what pushes the number up or down, and real GTA examples in our managed IT services pricing guide for Toronto.

Does a Small Business Need a Local GTA Provider?

Remote support resolves most day-to-day tickets, but three things still require a provider with people in your region: onsite response when hardware fails, someone who has physically seen your office and network closet, and accountability you can drive to. If your office is downtown, a provider delivering managed IT services in Toronto can put a technician on site the same day instead of couriering you a replacement router with a printout.

We see the difference most clearly with physical infrastructure. When a production-floor switch died at a Vaughan manufacturer we support, the fix was an engineer in a car with a spare in the trunk, not a remote session. That is the part of managed IT that a provider three time zones away simply cannot deliver. Being an IT company in Mississauga, headquartered in the middle of the GTA, means our average drive to a client site is measured in minutes, and it is why our onsite commitments hold up in practice.

Local also matters for compliance context. An Ontario provider works inside PIPEDA daily and understands what Canadian data residency requirements mean for where your backups live. A US-based remote MSP often does not.

How to Evaluate a Managed IT Provider: Six Questions to Ask

Every MSP demo looks the same. These six questions separate a defined service from a smooth sales call. Get the answers in writing.

Ask for the response SLA in writing: not “we’re usually fast,” but a contractual number by severity. (Ours is a 15-minute critical response SLA.)

Ask what’s out of scope: the exclusions list predicts your future invoices better than the price does.

Ask who owns security: which controls are included, which are add-ons, and who responds at 2 a.m. when something trips an alert.

Ask how backups are tested: a backup that has never been restored is a hope, not a plan. Ask for the restore-test cadence and the last test date.

Ask about onboarding and offboarding: how employees are set up and, more importantly, how access is revoked the day someone leaves.

Ask about exit terms: you should own your documentation, passwords, and data, and be able to leave without a hostage negotiation.

Managed IT services give a small business enterprise-grade support, security basics, and predictable cost for less than the price of one internal hire. The winning move is not finding the cheapest monthly fee; it is finding the provider whose written scope, SLA, and exclusions survive your six questions.

BALANCED+ has delivered managed IT services to Ontario businesses since 1994, from our Mississauga headquarters across Toronto and the GTA, and Canada-wide through our Vancouver office for BC clients. If you’re comparing providers, we’ll give you a free, no-pressure assessment of your current environment so you know exactly what a proposal should cover. Book a consultation or call 416.621.6611.

Sources

What Clients Never See: The Structure Behind a Healthy MSP Relationship

A few months ago, in a monthly review meeting, a client executive stopped me at an item on our risk list. It was a storage volume trending toward capacity, flagged and scheduled for remediation. He read it, looked up, and asked: “So what would have happened if you had not caught this?”

The honest answer was uncomfortable. You would have found out in about three weeks, probably during your busiest production window, and this would have been a very different meeting.

That question has stayed with me, because it gets at something most businesses quietly worry about but rarely say out loud: is my IT provider actually watching, or do they only show up when something breaks?

I work at a managed service provider. I spend most of my week embedded at client sites, and I have sat on both sides of that worry. So I want to open the hood and show what a healthy MSP relationship actually looks like from the inside. Not the version on the website. The version that happens at 7:30 in the morning when nobody is watching.

The morning nobody sees

Every working day starts the same way for me: a health check that runs before the client’s day does. Servers. Databases. Backup jobs from the night before. Network hardware. The phone system. Monitoring alerts that fired overnight.

It takes maybe forty minutes. Most days, nothing is wrong. And that is exactly the point.

Here is what years of doing this have taught me: serious problems almost never arrive out of nowhere. They announce themselves quietly, days in advance, in ways that are easy to miss if nobody is listening. A backup job that took twice as long as usual. A disk creeping toward full. A server that rebooted itself at 2 AM and came back fine, this time.

That storage volume from the opening? It was caught on a Tuesday morning during a routine check, when it was still just a line item on a spreadsheet. The alternative version of that story is a production floor standing still while everyone scrambles to figure out why orders stopped flowing. Same root cause. Completely different day.

The daily check is boring. I will not pretend otherwise. But boring, done every single day, is what prevention actually looks like. There is no dramatic version of catching a problem early. That is the whole idea.

A monthly meeting with no surprises

Once a month, I sit down with the client’s leadership for what we call a Service Delivery Review. On paper it is a status meeting: what happened, what is at risk, what is coming next. In practice it is something closer to a trust exercise.

Because here is the thing about these meetings. They are only comfortable if you have nothing to hide. Ticket volumes go on the table. Recurring issues go on the table. Things we got wrong go on the table too. If we misjudged a maintenance window or a fix took longer than it should have, the client hears it from me, in that room, with context.

I have come to believe the review is not really for the MSP at all. It is the client’s meeting. And there is one rule I hold myself to: if the client is hearing bad news for the first time in a monthly review, we already failed a step earlier. Bad news should travel fast, the same day it happens. The monthly meeting is where we look at patterns, make decisions, and plan ahead.

Good to know:

There is a quieter benefit to the cadence itself. A client who hears from their provider every month, in a structured way, never has to sit and wonder whether anyone is paying attention. That wondering is corrosive. It is where distrust starts, long before anything actually breaks.

Nothing changes without you knowing

One of the most valuable documents in any client relationship is also one of the least glamorous: a written change management process, approved by the client, that governs how anything in their environment gets modified.

Change management process

A change management process is an agreed set of rules for how any update, patch, or configuration change gets made in your IT environment. No change happens without the client knowing in advance, and every change has a scheduled window, a documented reason, and a rollback plan in case it goes sideways.

I will be honest about how this feels day to day. Process feels slow, right up until the first time it saves you. Then it feels like the only sane way to work.

But the real value is not technical. It is emotional. Without a change process, every hiccup turns into “IT did something and now this is broken,” which is a terrible sentence for everyone involved. With one, the conversation becomes “we agreed on this window, here is what we planned, here is what we are doing about it.” Same event. Entirely different relationship.

When things break anyway

I want to be straight about something, because this is where a lot of MSP writing gets dishonest. Structure does not prevent every incident. Hardware fails. Software has bugs. I have been on-site at 7:40 in the morning doing a cold restart of a server after a night nobody enjoyed. Anyone in this industry who tells you outages are a thing of the past is selling something.

What structure changes is everything that happens next.

From the client’s chair, a well-handled incident has a recognizable shape. Someone acknowledges the problem fast. Updates keep coming while things are still broken, even when the update is “we are still working on it, here is what we know so far.” And afterward, there is a written explanation of the root cause in plain English. Not jargon. Not a wall of log excerpts. A version the business owner can read and actually understand, because it happened to their business and they deserve to know why.

I have written those explanations after long nights, and I can tell you the temptation to hide behind technical language is real. Resist it. In my experience, clients do not lose trust because something broke. They lose trust when nobody can explain why, or when the same thing breaks twice and nobody connected the dots.

Being heard is a process, not a personality

Every MSP says some version of “we listen to our clients” or “we are proactive, not reactive.” I have said those words myself. But at some point I realized that being heard is not a soft skill. It is an output. It is what falls out of the structure when the structure is real.

Think about what the pieces add up to. The daily check means someone is watching your environment before you wake up. The monthly review means you are never in the dark about your own systems. The change process means nothing happens behind your back. The plain-English incident writeup means even the worst days end with understanding instead of confusion.

None of those pieces, individually, is impressive. Together, they are the answer to the fear I opened with. A charming account manager with no system behind them will eventually miss something that matters. A solid system makes even an ordinary Tuesday feel like someone has your back. Ideally you get both. But if I had to choose, I would take the system every time, because the system does not have bad weeks.

The question worth asking

If you work with an IT provider today, or you are evaluating one, here is a simple test. Do not ask about their tools or their certifications. Ask this instead: “Walk me through what you did for us last Tuesday.” Not last quarter. Last Tuesday.

A provider with real structure can answer in detail: the morning checks that ran, the alerts reviewed, the changes scheduled, the tickets closed. A reactive provider will talk about their general approach, because on any given Tuesday where nothing broke, they were not thinking about you at all.

And that brings me back to that question from the review meeting. “What would have happened if you had not caught this?” It is a fair question, and I never mind answering it. But the best measure of a healthy MSP relationship is that with the right structure in place, it is a question you rarely have to ask.

This is what our managed IT services are built around: daily monitoring, monthly service reviews, and a change process that keeps you in the loop. If you are wondering whether your current provider is watching or just waiting for the phone to ring, that is a conversation worth having. Get in touch and we will walk you through what our week looks like.

Human Error Remains the Biggest Cybersecurity Risk

You can spend six figures on firewalls, endpoint protection, and round-the-clock monitoring and still get breached because one employee granted access to someone they believed was IT support. That is not a hypothetical. It is the most common way Canadian mid-market businesses get compromised, and in most cases the security tools were working exactly as designed when it happened.

This post covers why human error is still the leading cause of cyber incidents, the social engineering threats your organization faces today, and the practical steps that actually lower the risk.

Human error remains the biggest cybersecurity risk because attackers have shifted their focus from breaking technology to manipulating people, and people are far easier to fool than modern security tools are to defeat. Social engineering, from phishing emails to fake IT-support requests for remote access, along with weak or reused passwords, bypasses technical controls by targeting the person holding the keys. The organizations that stay secure treat their staff as part of the defence, pairing layered technology with continuous training so a single mistake does not turn into a breach.

Human Error (in Cybersecurity)

In cybersecurity, human error is any unintentional action, or failure to act, by a user that gives an attacker an opening: granting remote access to an impostor, clicking a malicious link, reusing a password, or sending sensitive data to the wrong recipient. It is distinct from malicious insider activity because there is no intent to cause harm, which is exactly why it is so hard to defend against with technology alone.

Why do attackers target people instead of systems?

Because it works, and it is cheaper. A modern security platform that is patched and configured correctly is genuinely hard to break. A distracted employee at 4:45 on a Friday is not. Rather than spend weeks hunting for a software vulnerability, attackers reach people directly by email, phone, chat, or a remote-support tool, ask them to approve a request or grant access, and let normal human behaviour do the rest.

68%

of data breaches involved a human element such as error, misuse, or social engineering (Verizon 2024 Data Breach Investigations Report)

We see this pattern directly. When we run a baseline social engineering test for a new GTA client before any training, the number of staff who engage with a convincing request commonly lands between 20 and 30 percent. These are not careless people. They are busy staff who have never been shown what a modern attack actually looks like, and that gap is what attackers monetize. According to the Verizon 2024 Data Breach Investigations Report, the human element is a factor in roughly two-thirds of all breaches, a figure that has barely moved despite years of improving security technology.

What are the most common social engineering threats?

Social engineering is the common thread behind most human-driven incidents, whether it arrives as a phishing email, a fake IT-support request, or a phone call. It works by getting a legitimate user to act on the attacker’s behalf, which is why it slips past tools built to stop malicious code. Weak passwords then compound the problem by turning one successful trick into access across multiple systems.

Social Engineering

Social engineering is any attack that manipulates a person into granting access, revealing information, or taking an action that helps the attacker, rather than exploiting a technical flaw. It spans phishing emails, fraudulent phone calls, text messages, and impersonation over chat or remote-support tools. Because it targets human trust instead of software, it routinely bypasses technical defences.

ThreatHow it exploits peopleFirst line of defence
PhishingFake emails, websites, and messages that impersonate trusted brands or colleagues to steal credentials or deliver malwareUser training plus email filtering and MFA
IT-support impersonationAttackers pose as internal IT or a trusted vendor over chat or remote-support tools and request access to a workstationVerify every unexpected access request through a known channel
Weak passwordsReused, predictable, or shared passwords let one leaked credential unlock multiple accountsA password manager, enforced complexity, and MFA

A single successful trick often becomes the foothold for a wider campaign, which is why we treat social engineering defence as the foundation rather than one item on a checklist.

Warning:

Attackers increasingly use AI to write flawless, personalized messages, so the old advice to “watch for spelling mistakes” no longer holds. A message can be grammatically perfect, reference a real project, and still be fraudulent. Verification habits matter more than spotting typos.

How do attackers impersonate IT support?

A fast-growing social engineering tactic skips email entirely: the attacker contacts a user directly through a chat or remote-support tool, claims to be from IT or a trusted vendor, and asks for remote access to fix an urgent problem. The channel is what makes it effective. A message in Microsoft Teams or a session request through a tool like ScreenConnect feels far more legitimate than a cold email, so the usual phishing instincts never fire.

Once a user grants access, the attack moves fast. An impostor with a live remote session can install malware, copy sensitive data, and disconnect within minutes, often before anyone realizes the “support technician” was never from IT. Because none of this touches the email gateway, email-based phishing training does nothing to stop it. This is exactly why awareness has to extend beyond the inbox to every channel a user can be reached on.

Warning:

Treat any unexpected request for remote access as hostile until proven otherwise, whether it arrives by email, phone, Microsoft Teams, or a remote-support tool such as ScreenConnect. Verify it through a known IT contact or your ticketing system before granting access. A real technician will never object to being verified.

Why isn’t security technology enough on its own?

Because every technical control still has a human in the loop, and that person can be persuaded to open the door. Firewalls, endpoint detection, and multi-factor authentication all raise the cost of an attack, but a user who approves a fraudulent MFA prompt or hands remote control to a fake technician has just walked the attacker past those defences. Technology narrows the attack surface; it does not remove the person standing in the middle of it.

99.9%

of automated account-compromise attacks are blocked by enabling multi-factor authentication (Microsoft)

That does not make the technology optional. Multi-factor authentication alone blocks the overwhelming majority of automated account attacks, according to Microsoft. The point is that controls and people reinforce each other. Layered technology catches the mistakes training misses, and trained users catch the attacks that slip past the tools.

Move your organization to phishing-resistant MFA (hardware keys or passkeys) for administrators and finance staff first. These accounts are the highest-value targets, and app-based push approvals can still be defeated by MFA fatigue attacks where a user taps “approve” just to stop the notifications.

How do you build a security-aware culture?

You build a security-aware culture by making safe behaviour routine and easy, not by running a once-a-year training video and hoping it sticks. The goal is an organization where staff recognize common attacks across every channel, follow simple verification habits, and feel safe reporting a mistake immediately. The following steps are the ones we put in place for clients, in order of impact.

Train regularly, in short sessions: Replace the annual marathon with brief, frequent refreshers covering email, phone, and chat-based attacks. People retain more from ten focused minutes each month than from a single long session they forget by lunch.

Verify every remote-access request: Teach staff that no one approves remote control of their workstation from an unexpected message or call, no matter how urgent it sounds. Confirm through a known IT contact or a ticket first, regardless of the channel it came through.

Run social engineering simulations: Send realistic phishing tests and, where possible, simulate impersonation attempts, then measure engagement and report rates. Simulations turn an abstract risk into a concrete, improvable number and show staff what a real attack feels like in a safe setting.

Enforce strong passwords and MFA: Require a password manager, block reused and breached passwords, and turn on multi-factor authentication everywhere it is available, starting with email and privileged accounts.

Make reporting easy and blameless: Give staff a one-click way to report a suspicious message or call, and thank them when they do, even for false alarms. The faster a real attack is reported, the smaller the damage.

This works. Across the clients where we run continuous simulations and short monthly training, we typically see engagement with test attacks fall from that 20 to 30 percent baseline into the single digits within a few cycles, and report rates climb at the same time. The cost of that program is trivial next to the alternative. IBM puts the global average cost of a data breach at US$4.88 million in 2024.

US$4.88M

average total cost of a data breach in 2024, the highest on record (IBM Cost of a Data Breach Report 2024)

The bottom line

The strongest cybersecurity strategy combines advanced security technology with continuous employee education. Technology alone cannot stop social engineering that convinces a person to open the door, whether by email, phone, or a remote-support tool, and awareness alone cannot catch what slips through. Reducing human error is the highest-leverage move most organizations can make to lower the risk of a successful attack and strengthen their overall security posture.

BALANCED+ is a Fortinet Authorized Partner, and our security engineers hold Fortinet NSE certifications, but we tell every client the same thing: the technology is only half the job. Our managed cybersecurity team runs social engineering testing and awareness training alongside the firewalls, monitoring, and MFA, so your people become a layer of defence rather than the weakest link. If you want to see where your staff stand today, a baseline social engineering assessment is a low-effort place to start.

Sources